🎓 Open to 2027 New Grad Roles | China & Hong Kong

MD RAKIBUL ISLAM RAIHAN

|

LLM Inference Systems | GPU Optimization | Multimodal AI Research

NWPU Top 1% Chinese Gov Scholarship IEEE TNNLS Under Review
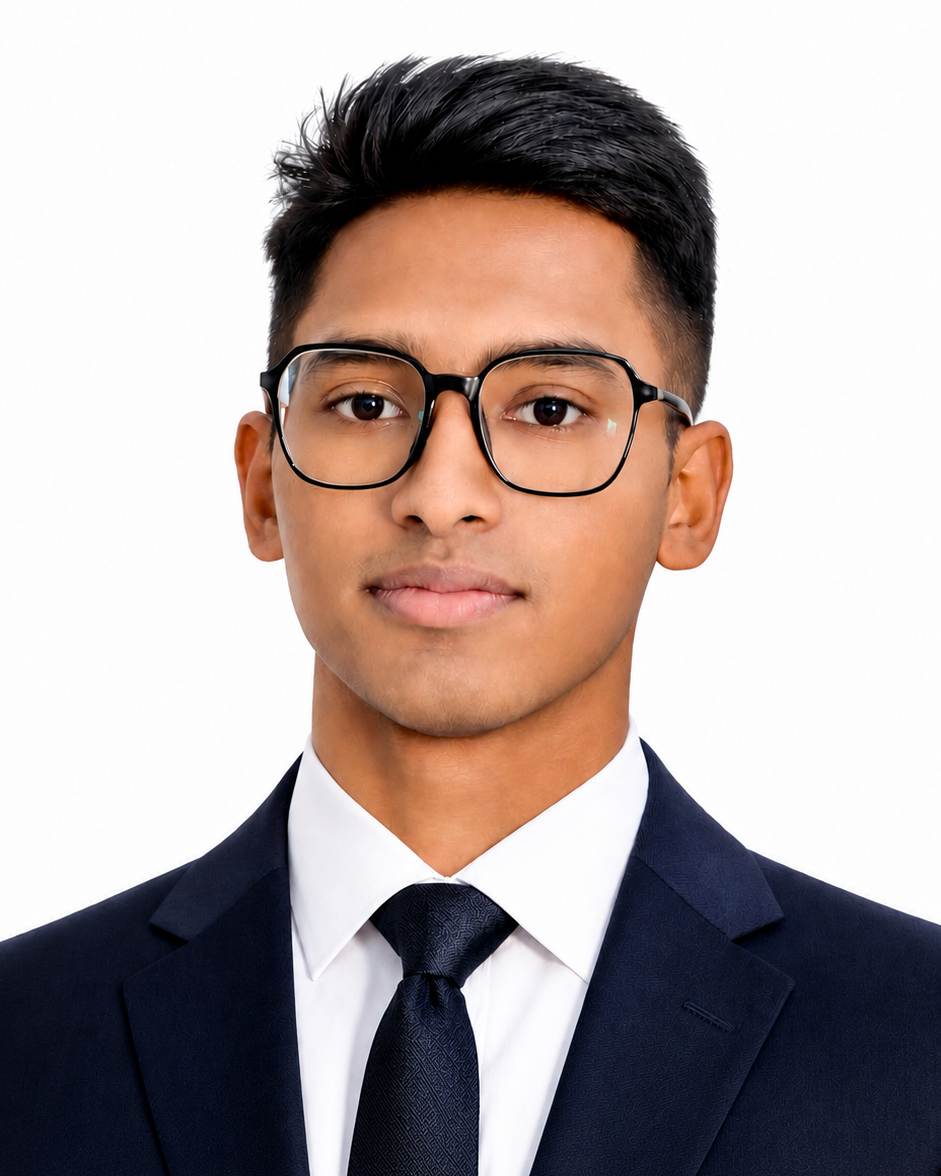
MD RAKIBUL ISLAM RAIHAN
92.27%
KV-cache hit rate
8.3×
TTFT reduction (4×A800 PD)
4×
Memory (FP4 / NVFP4-DiT)
10
Production OSS repos

About Me

⚙️

AI Infrastructure

Designed 3-tier KV-cache (GPU→CPU→SSD) with SGLang + RDMA achieving 92.27% hit rate and 8.3x TTFT reduction on 4xA800.

📊

Research

First author IEEE TNNLS paper on NVFP4-DiT — 4-bit quantization for video diffusion achieving 4x memory reduction.

🎓

Education

M.Eng. Software Engineering @ NWPU (985/211), Top 1%, GPA 88/100. Chinese Government Scholarship.

Experience

AI Infrastructure Engineer Intern

InfiX.ai | Shenzhen | Apr 2026 – Jun 2026

  • Designed 3-tier KV-cache (GPU HBM → CPU DRAM → SSD) with SGLang + Mooncake RDMA — 92.27% hit rate, 8.3x TTFT reduction (55s→6.7s)
  • Patched SGLang source (kvcacheio.py, hiradix_cache.py) for hybrid-attention Qwen on 4xA800
  • Built PD-disaggregated serving with RDMA KV sharing — concurrency 192→256
  • Profiled CUDA/Triton with Nsight Systems, FP8 optimization
  • Resolved 12+ production issues (RDMA, etcd, networking)

Software Engineer Intern (AI Agent)

Hong Kong Amram Group | Shenzhen | Jun 2025 – Sep 2025

  • Full-stack apps with React, REST APIs, backend automation
  • AI-agent workflow automation improving efficiency by 25%

Electrical Software Engineer Intern

Shaanxi Longong | Xi’an | Feb 2025 – Apr 2025

  • PLC industrial control systems with CODESYS for robotics
  • Modbus, CAN, Ethernet/IP — motor performance +15%

Research & Publications

IEEE TNNLS (Under Review)

NVFP4-DiT: 4-Bit Audio-Guided Video Diffusion

First author. 4x memory reduction with FP4 quantization for multimodal diffusion transformers.

GitHub →
M.Eng. Thesis

Multimodal Deepfake Detection

EfficientNet+FFT + MFCC + Transformer with attention fusion for multimodal deepfake detection.

Thesis PDF →
B.Eng. Thesis

Distributed Confidential Query

Apache Spark + CKKS homomorphic encryption. 95% privacy preservation, 20% performance gain.

Thesis PDF →

Open-Source Contributions

SGLang | Open PR

KV-cache eviction unit tests

Added unit tests for KV-cache eviction priority strategies in sgl-project/sglang (PR #31121) — directly relevant to production LLM serving.

View PR →
Active OSS Contributor

Upstream & community

Opened PRs and doc/typo fixes across multiple open-source projects (SGLang, SDKs, developer tooling), building a consistent public contribution history.

GitHub →

Featured Projects

Technical Skills

Languages

PythonC++JavaSQLBash

LLM Systems

SGLangvLLMTensorRT-LLMKV CachePD DisaggMooncake RDMAetcd

GPU & ML

CUDATritonFlashAttnFP8/FP4GEMMNsightPyTorch

Infra

LinuxDockerK8sSlurmRDMAPrometheusGrafanaCI/CD

Web & Tools

ReactREST APINode.jsGitCODESYSModbusCANEthernet/IP

Research

Deepfake DetectionDiffusion ModelsHomomorphic EncryptionSparkNsightGrad-CAM

M.Eng. Software Engineering

NWPU (985/211)

Sep 2024 – Mar 2027 | GPA 88/100 (Top 1%)

Thesis PDF →

B.Eng. Computer Science

NWPU (985/211)

Sep 2020 – Jul 2024 | GPA 85/100 (Top 1%)

Thesis PDF →
🏆 Chinese Gov Scholarship 🏆 Presidential Scholarship 🏆 Best Thesis Award 🏆 Outstanding Graduate 🏆 Hackathon Winner

Research Interests

🧠

AI Infrastructure

LLM inference systems, KV-cache architecture, PD disaggregation, RDMA-based distributed serving on multi-GPU clusters.

🎥

Multimodal AI

Visual + audio + temporal fusion, deepfake detection, audio-guided video generation, cross-modal attention mechanisms.

⚡

LLM Optimization

Low-precision quantization (FP8/FP4), CUDA/Triton kernel optimization, FlashAttention, GEMM acceleration for inference.

Open to collaboration on LLM serving, multimodal AI, and GPU optimization. Reach out via email or LinkedIn.

Get in Touch